Skip to content

Quantization & Formats

3 Topics 3 Posts

GGUF, EXL, AWQ, GPTQ, FP8, bitsandbytes.

This category can be followed from the open social web via the handle quantization-formats@airigs.net

  • 8-bit KV Cache on Ampere

    1
    0 Votes
    1 Posts
    12 Views
    F
    When using vLLM on Ampere GPUs, you may see that when selecting 8bit quantization formats for kv cache (fp8, int8) it falls back to other inference engines (Flashinfer, Triton Attention). In my experience, Triton Attention performs very poorly on Ampere, especially on higher contexts, and Flashinfer doesn't work with DFlash2, which is most likely why these alternatives were made: (both available in the HyperQwen repository). For FP8 KV Cache -> There's a fork of Flash Attention 2 with fp8 kv cache. For Int8 KV Cache -> Use the 'PTH' option in HyperQwen. In my experience, FP8 performed better at prefill and Int8 performed better at decode, both work with DFlash2 with solid results.
  • EXL3

    1
    3
    0 Votes
    1 Posts
    51 Views
    F
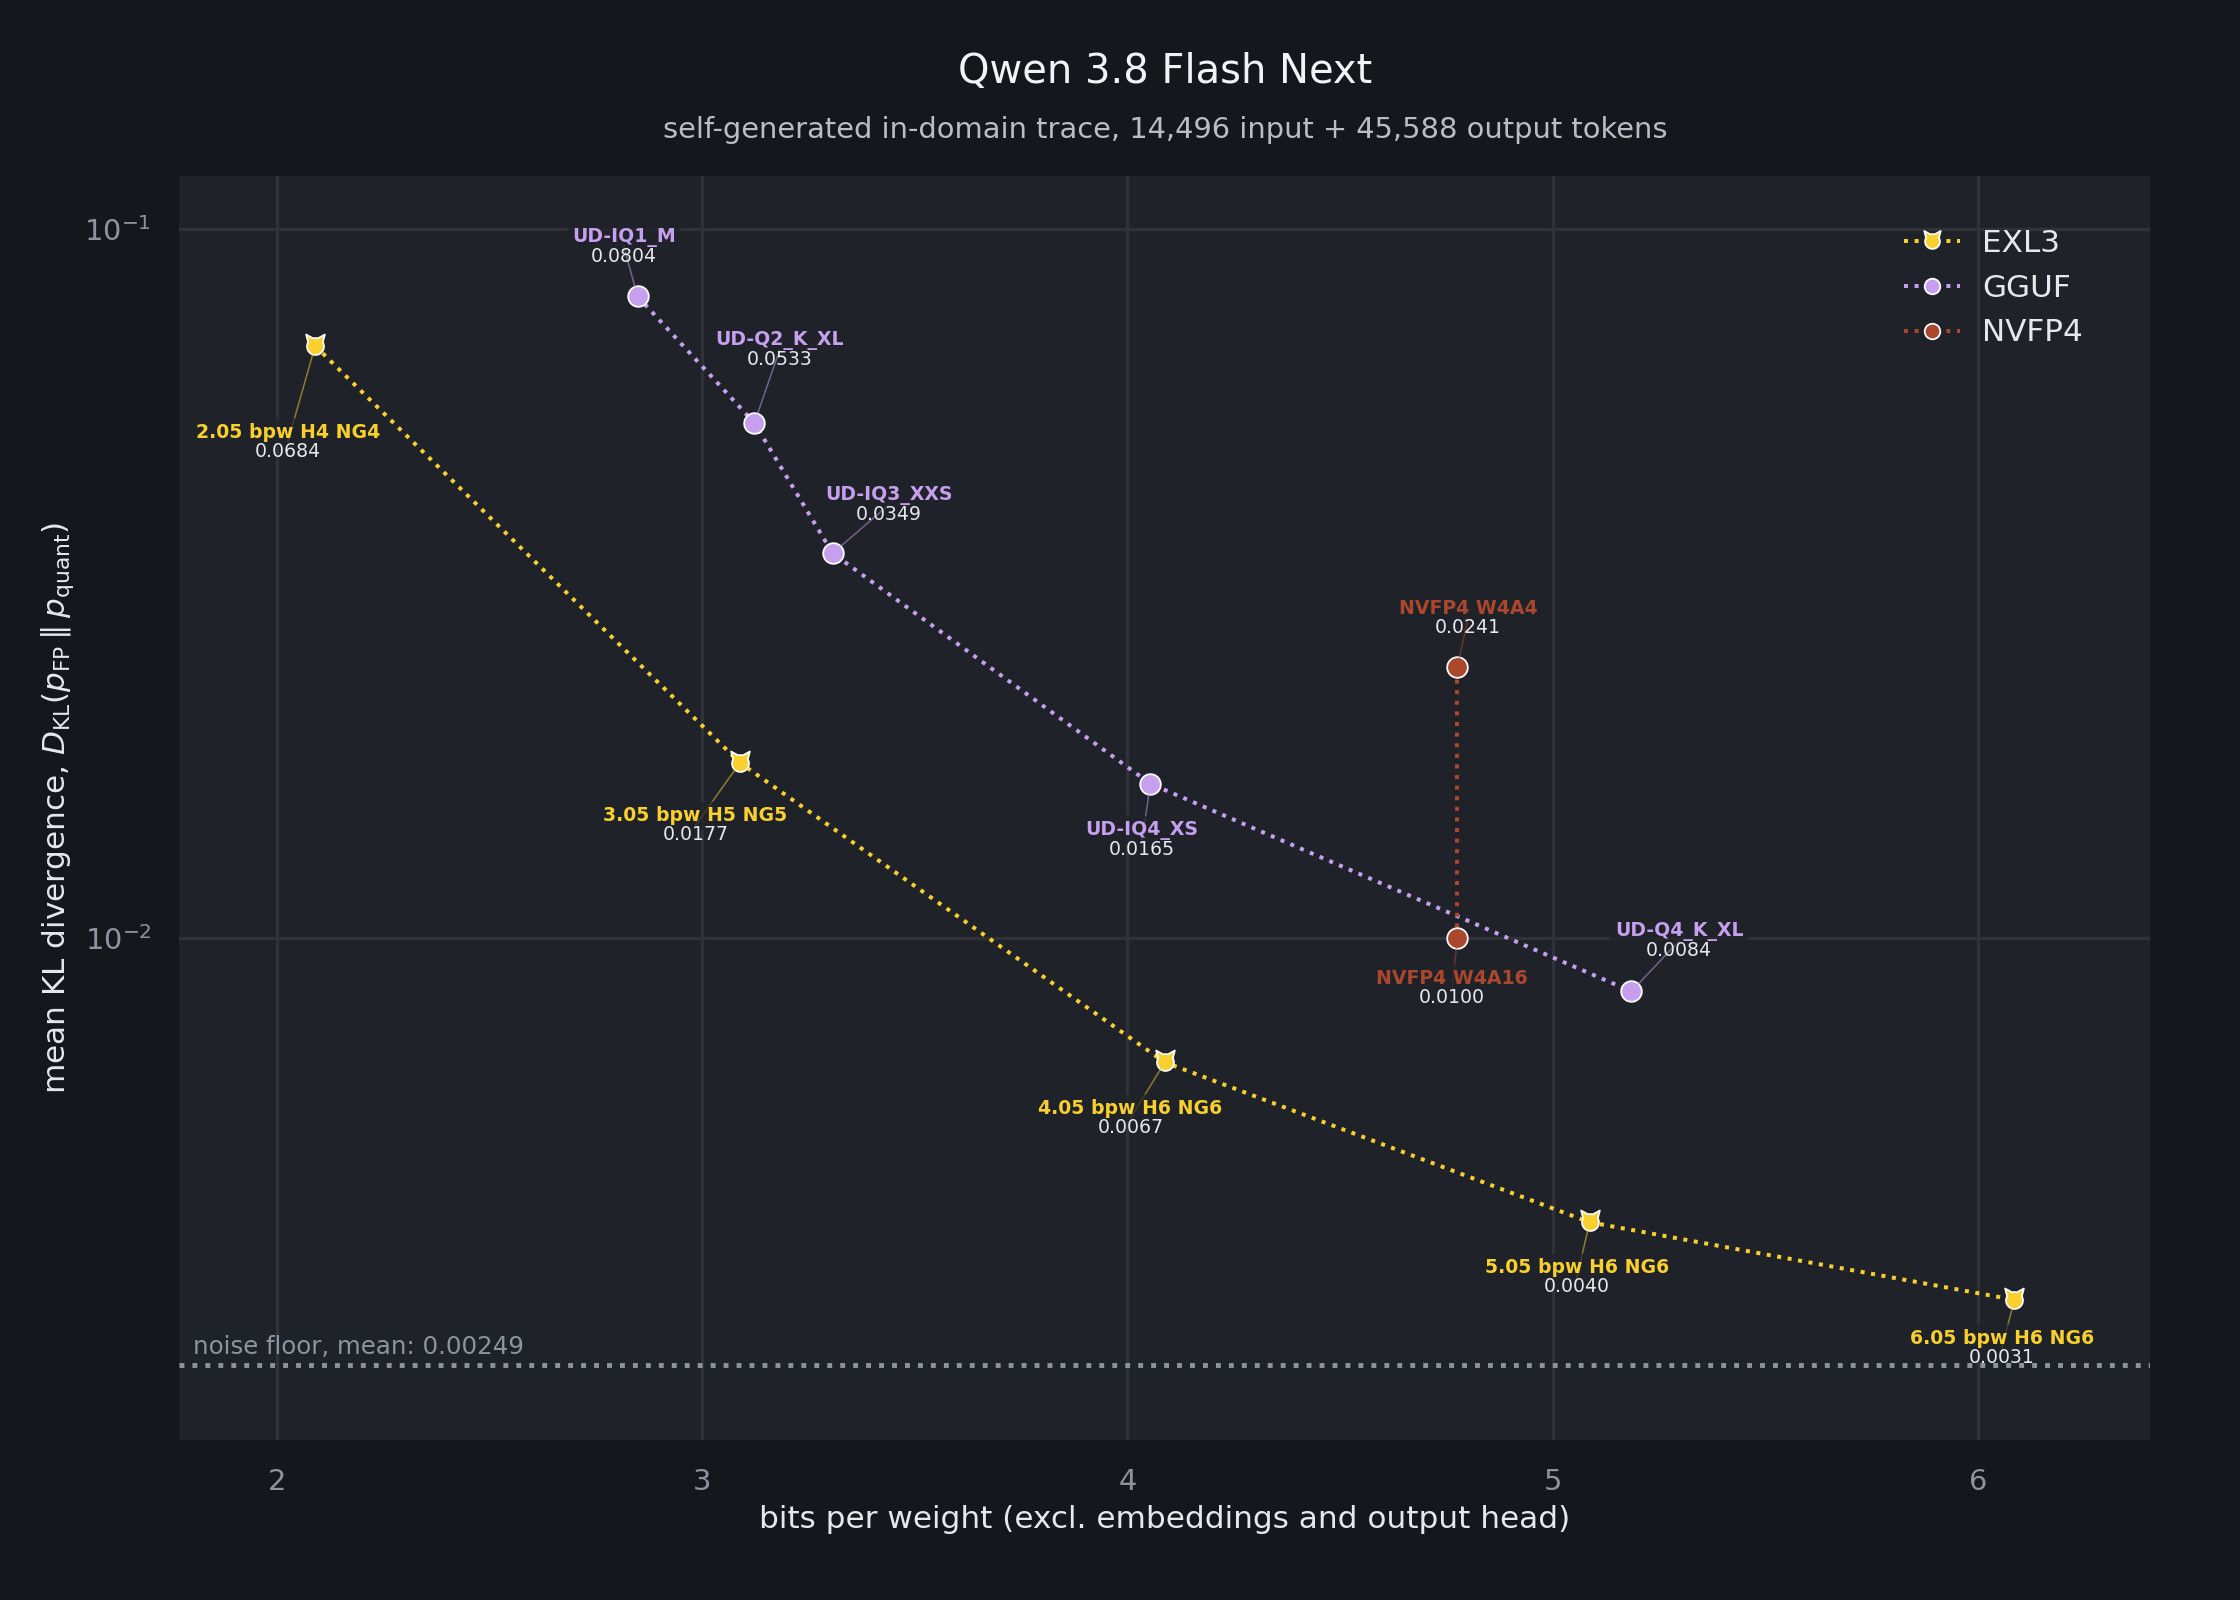
    Seems to be objectively one of the BEST quantization formats as of now, with the added benefit that the inference engines run much better than llama.cpp (GGUF) for CPU offload. For example, numbers on Qwen3.8-Flash-Next-exl3: [image: image.jpeg] [image: image.jpeg] [image: image.jpeg]
  • VLLM with mixed quantization

    1
    2
    0 Votes
    1 Posts
    60 Views
    F
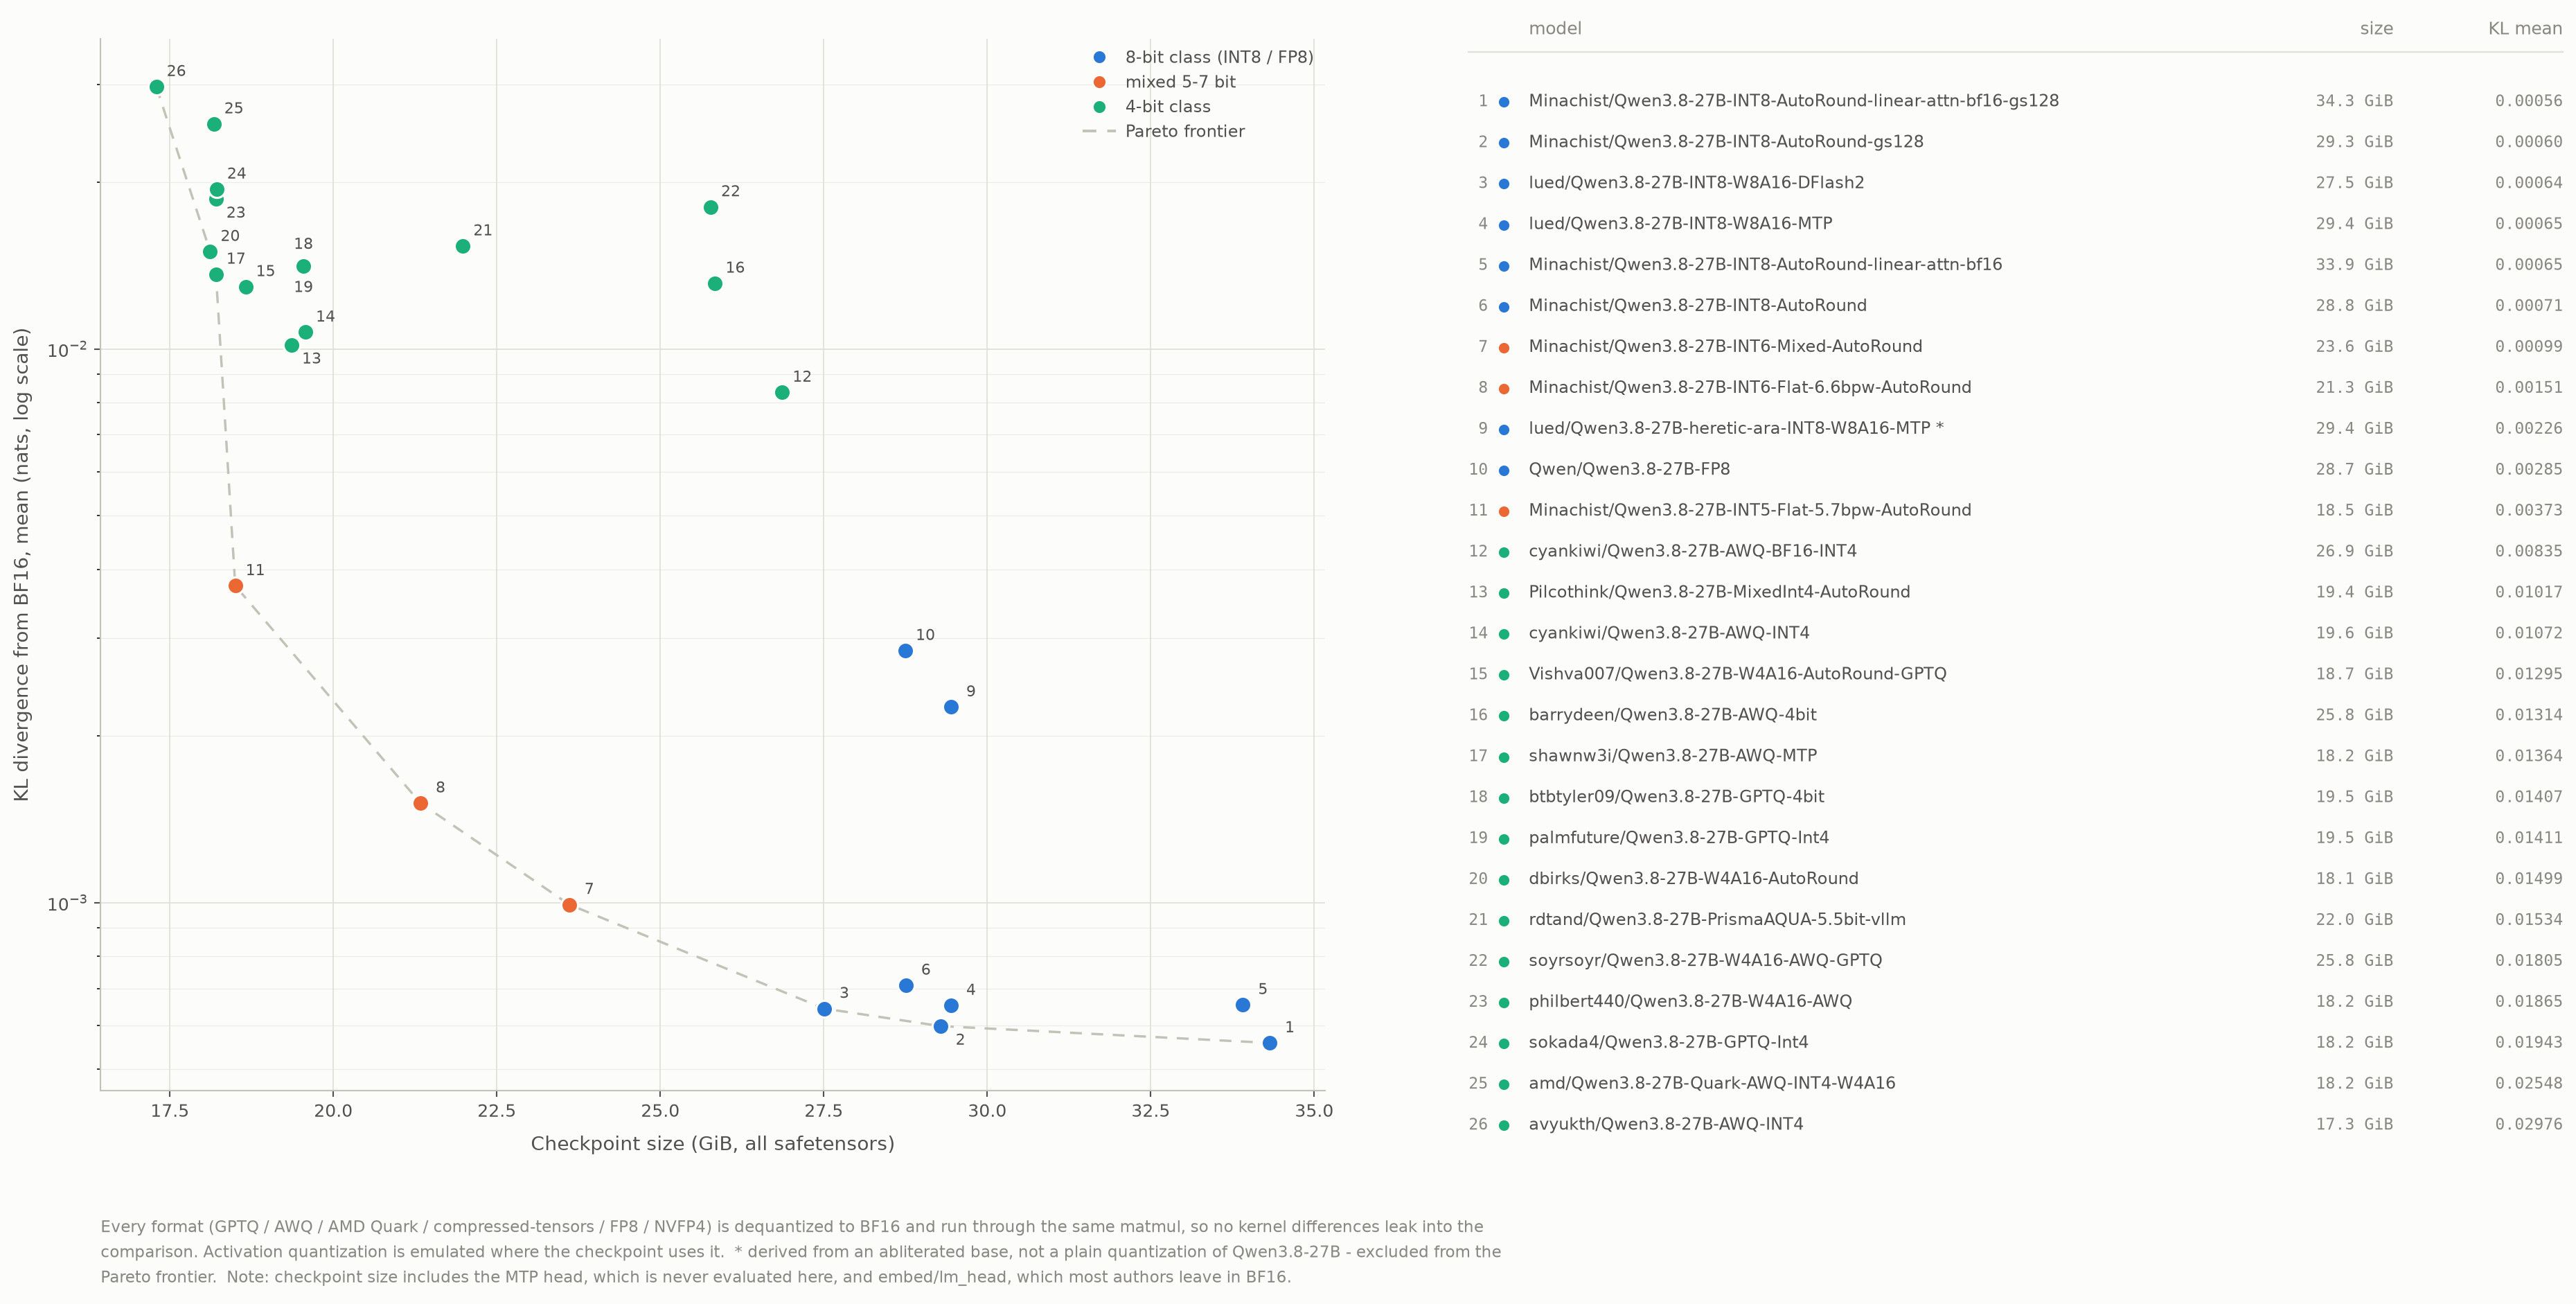
    Findings from Minachist's huggingface profile. Before anything, there's a really good blog post detailing the internals in Minachist's blog, found here. Turns out these quantizations are the best I've found (compared to their size, for vLLM) by a HUGE margin, (photos from the blog linked above): [image: image.jpeg] [image: image.jpeg] Sources (and good quantizations/resources): https://minamism.com/posts/vllm-int5-7-quantization/ https://huggingface.co/Minachist/Qwen3.8-27B-INT6-Mixed-AutoRound https://huggingface.co/Minachist/Qwen3.8-Flash-Next-INT4-Mixed-AutoRound