F
fedes1to
@fedes1to
Topics
-
CMP 170HX is a strong (when unlocked) card
Watching Ignoring Scheduled Pinned Locked Moved GPUs & Accelerators0 Votes1 Posts9 Views -
Unlock your GPU for free performance (RTX 20/30/40)
Watching Ignoring Scheduled Pinned Locked Moved GPUs & Accelerators0 Votes1 Posts3 Views -
0 Votes1 Posts15 Views
-
8-bit KV Cache on Ampere
Watching Ignoring Scheduled Pinned Locked Moved Quantization & Formats0 Votes1 Posts12 Views -
Nanobot
Watching Ignoring Scheduled Pinned Locked Moved Agents & RAG0 Votes1 Posts60 Views -
What's an MoE, and why should I care?
Watching Ignoring Scheduled Pinned Locked Moved Local LLMs0 Votes1 Posts60 Views -
New to Local LLMs? Start here!
Watching Ignoring Scheduled Pinned Locked Moved Local LLMs0 Votes1 Posts64 Views -
New to Local AI? Start here!
Watching Ignoring Scheduled Pinned Locked Moved Announcements0 Votes1 Posts103 Views -
Strata: Run decent models on small hardware
Watching Ignoring Scheduled Pinned Locked Moved Runtimes & Serving Stacks0 Votes1 Posts58 Views -
Modified NVIDIA GPUs
Watching Ignoring Scheduled Pinned Locked Moved GPUs & Accelerators0 Votes1 Posts75 Views -
Stop using Ollama, please.
Watching Ignoring Scheduled Pinned Locked Moved Runtimes & Serving Stacks0 Votes1 Posts41 Views -
Hardware specs website
Watching Ignoring Scheduled Pinned Locked Moved GPUs & Accelerators0 Votes1 Posts33 Views -
Qwen 3.8 Flash Next on RTX 3090's
Watching Ignoring Scheduled Pinned Locked Moved Throughput & Latency0 Votes1 Posts61 Views -
0 Votes1 Posts51 Views
-
ReBAR "alternatives" for modified GPUs
Watching Ignoring Scheduled Pinned Locked Moved Drivers, CUDA & ROCm0 Votes1 Posts58 Views -
VLLM with mixed quantization
Watching Ignoring Scheduled Pinned Locked Moved Quantization & Formats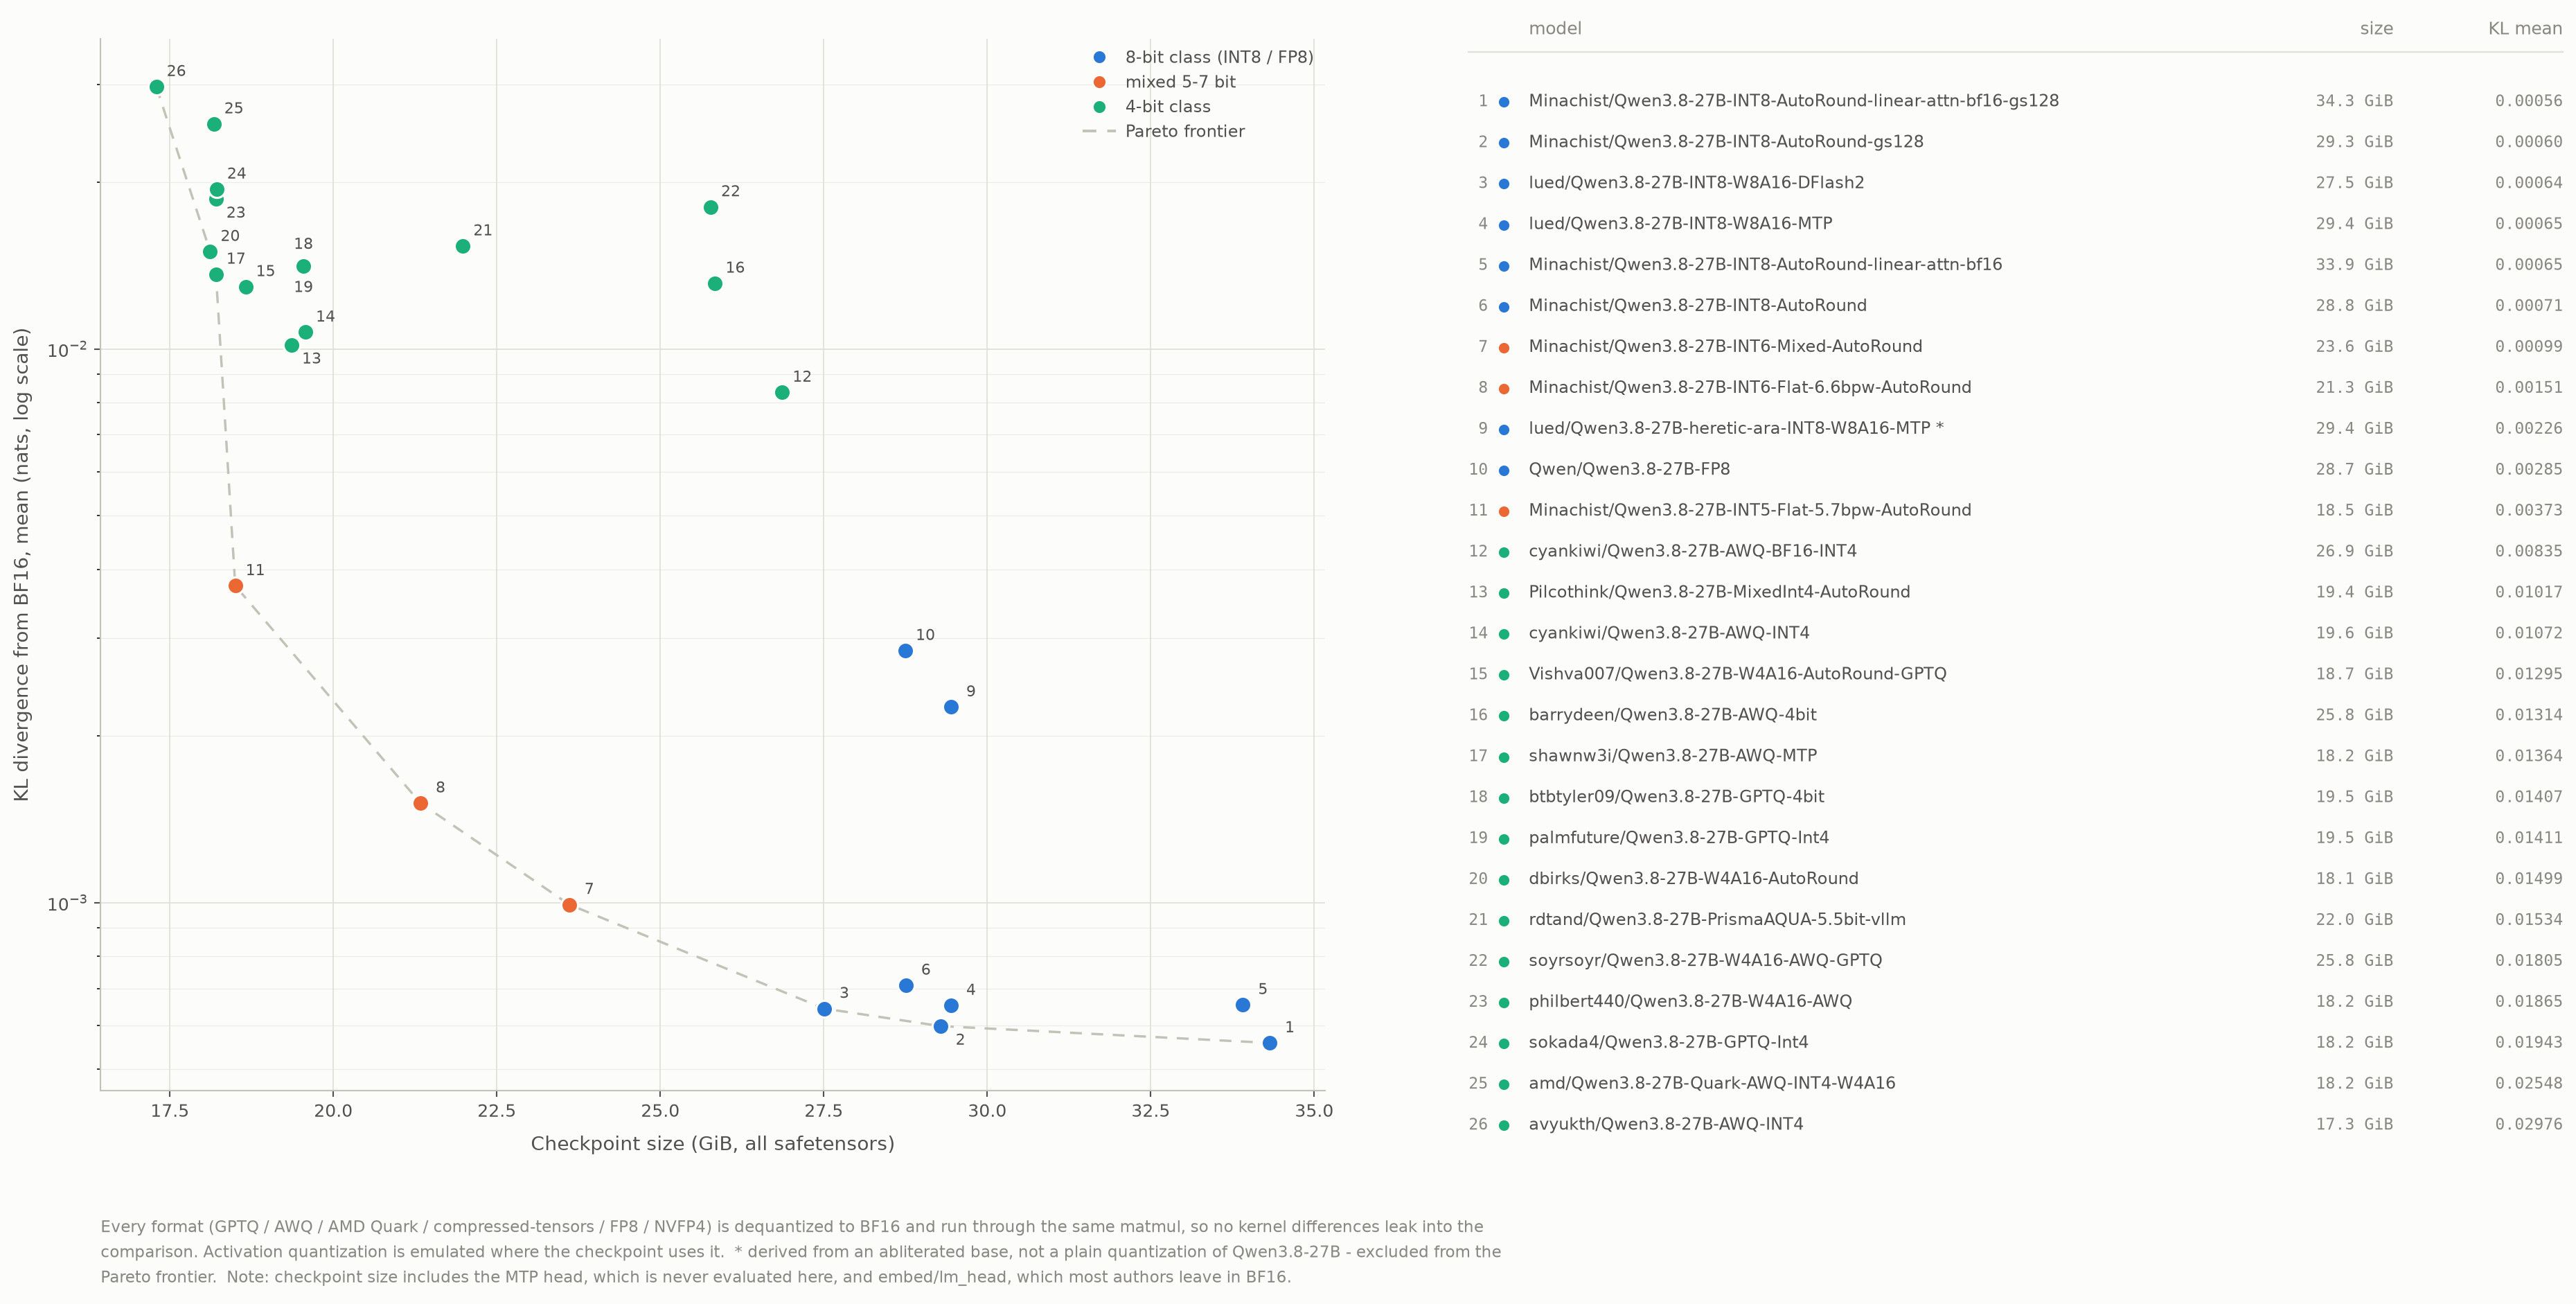 2
0 Votes1 Posts60 Views
-
NUMA aware inference with lk_moe / lvllm / lsglang
Watching Ignoring Scheduled Pinned Locked Moved Runtimes & Serving Stacks0 Votes1 Posts42 Views